Explore testing inside your project ->
MCP-powered testing routes: how BYOB connects runtime and browser #
Every important phone call needs both parties dialed into the same line. BYOB testing has two parties, the project runtime that serves your app and the browser extension that clicks through it, and the MCP route is the shared line. When both ends bind to the same route, test reports describe your product. When they drift apart, reports describe the plumbing, with false failures from unreachable paths and false passes against the wrong target.
This guide explains that route path as engineering workflow, not marketing shorthand.
TLDR #
- Test init returns MCP connection metadata.
- Frontend normalizes route details for browser context.
- Bridge signal is sent to extension via event and fallback channel.
- Extension connects and executes checks against correct runtime.
What does the architecture look like in one view? #
The protocol underneath follows the Model Context Protocol specification, where hosts, clients, and servers communicate over JSON-RPC with negotiated capabilities. MCP servers expose resources, prompts, and tools; clients consume them. BYOB's testing bridge borrows that shape: the runtime exposes the app, the extension consumes it through a negotiated connection, and the route metadata is what introduces them.
Why does MCP route data matter for test results? #
A test runner pointed at runtime A while the extension drives runtime B produces the worst kind of output: confident and wrong. Symptoms follow a pattern.
- false failures from unreachable paths
- false passes from the wrong target
- random timeout behavior that nobody can reproduce
Route binding eliminates that mismatch class entirely. The run carries its own connection metadata from birth, so every check executes against the runtime the run belongs to. Think of a switchboard operator who refuses to connect the call until both extensions confirm the same line. Slightly slower to start, dramatically more trustworthy afterward.
How does local development mapping behave? #
Local setups create a addressing wrinkle. The backend may return internal network addresses that the browser cannot reach directly, like a container hostname meaningful inside Docker but gibberish to Chrome. BYOB maps these to localhost equivalents when needed.
This mapping is not a hack. It is a practical adaptation for browser network reality, and the mapping decision itself gets logged so diagnostics can retrace it. Hosted environments skip most of this, which is why local mapping edge cases dominate support threads. Same system, different visibility.
How does bridge signaling reach the extension? #
BYOB sends bridge intent through two channels.
| Channel | Role |
|---|---|
| CustomEvent | Primary route in app context |
| postMessage | Compatibility fallback for integration edge cases |
A CustomEvent, the DOM interface for application-defined events carrying custom data, fires first inside the app context with the route payload attached. If the extension misses it due to timing or isolation boundaries, postMessage follows as backup. MDN documents postMessage as the controlled mechanism for cross-context messaging, with origin checking as the security load-bearing wall: always verify the sender's origin, always specify an exact target origin. The bridge follows both rules, which is why the fallback adds reliability without opening holes.
If runs stall in connecting phase, inspect bridge event flow before debugging application logic.
What breaks most often and how do you diagnose it? #
| Failure mode | Typical symptom | First check |
|---|---|---|
| Missing MCP URL | Run never enters active testing | Init response payload |
| URL not browser-reachable | Repeated connection timeout | Local mapping decision |
| Extension not listening | No bridge acknowledgment | Extension lifecycle state |
| Stale session metadata | Intermittent route mismatch | New session init and retry |
Read the table top to bottom during triage. Most "testing is broken" reports die at row one or two: the init payload lacked a route, or the mapped URL never answered from the browser's network position. Application logic sits several layers above; debug downward from the wire, not upward from the symptom.
What is in the debug runbook? #
- Confirm init payload includes MCP route.
- Confirm mapped URL is reachable from browser host.
- Confirm extension receives connect event.
- Confirm connection handshake completes before tests start.
- Retry with fresh session after any connection config changes.
Step 5 deserves respect. Stale sessions are the gremlins of this system. Config changed, container restarted, port shifted, and the old metadata still points at the old world. Fresh init costs seconds and clears the entire failure class.
What are the security and isolation notes? #
Route data stays scoped to the session lifecycle. Session metadata expires instead of lingering. Reuse across unrelated sessions gets blocked, so one project's route never leaks into another's run. Logs capture connection errors without exposing secrets, because diagnostics should explain failures without becoming an attack surface.
MCP connectivity should be observable but not overexposed. The MCP spec's security section sets the tone: explicit user consent for data access and tool invocation, least privilege throughout. The testing bridge inherits that posture.
Which observability signals are worth tracking? #
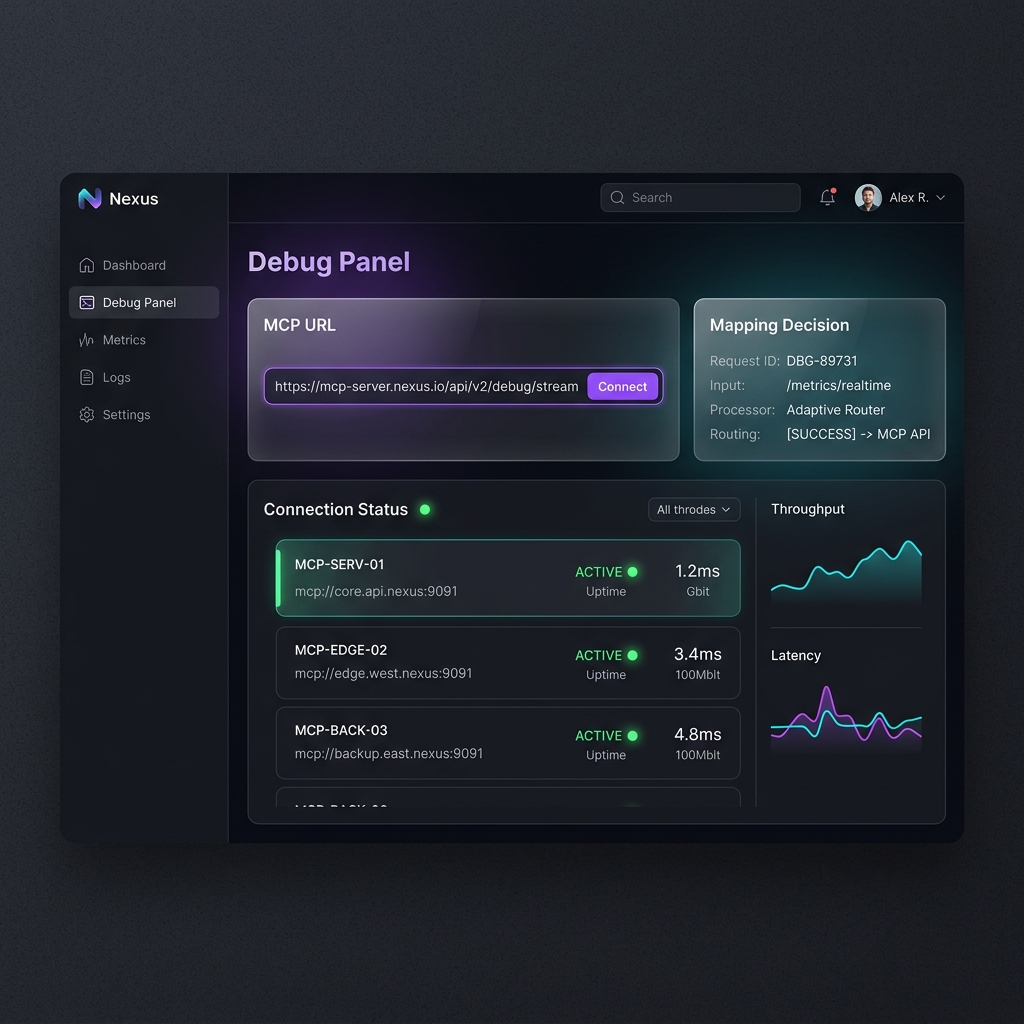
Track bridge health as first-class engineering metrics, separate from product test results.
- session init success rate
- extension handshake success rate
- average connection setup time
- timeout frequency by environment
These signals separate infrastructure quality from product quality. When handshake rates dip but product code never changed, the team investigates the bridge, not the app. Without this split, every infra hiccup masquerades as a product regression and wastes the most expensive debugging hours.
Why does this improve release confidence? #
Reliable route binding means failures are more likely real product issues rather than infrastructure noise. That distinction compounds: fewer wasted investigations, faster triage, reports the team actually believes. And belief matters. A test suite nobody trusts gets ignored, and an ignored suite is just electricity converted into log files.
The browser layer underneath follows industry standards all the way down. Tools like Playwright drive real browsers across engines with isolated contexts, and the W3C WebDriver spec standardizes the wire protocol for sessions, element interaction, and screenshots. BYOB's extension checks belong to that lineage, with MCP routing added so the right browser meets the right runtime every single run.
Try it: Deploy checklist
What are the trade-offs? #
MCP route metadata plus the dual channel bridge wins when failures must describe the product rather than the plumbing. Init returns the connection route, the frontend normalizes it, and checks run against that exact runtime in local and hosted environments.
| Pick the bridge when | Pick manual checks when |
|---|---|
| Extension and runtime must agree on the same target | The run is a one off visual glance at a static page |
| Local mapping edge cases need a repeatable path | The mapped URL is unreachable and a direct URL works |
| Release confidence needs route tied evidence | Only user facing copy changed and nothing stateful moved |
It loses on stale metadata. Expired sessions and unreachable mapped URLs are the common breaks, fixed by fresh init and reachability checks per the MCP spec and Playwright docs. Pick the alternative when the bridge itself is the suspect: reinit, verify the route, then run.
What we learned building this #
The dashboard carries the test panel that requests route metadata when it opens. Bridge signaling tries a direct event first with a message fallback, which matches the debugging order in the runbook above. Fresh sessions fix most stalls because stale route metadata is the usual suspect.
Who this is for (and who should skip it) #
This guide helps builders who run browser tests inside BYOB and triage stalls themselves. If connecting phase hangs or reports smell like plumbing instead of product, the runbook above tells you where to look first.
Skip the internals if you only click test and read the verdict. The system handles routing for you, and you can return here on the day a run misbehaves.
- Best for developers debugging stuck BYOB test runs.
- Best for small teams triaging browser faults without guessing.
- Best for startups wanting release confidence from test reports.
FAQ #
Is MCP route behavior only for local development? #
No. It matters in both local and hosted environments, but local mapping edge cases are more visible. Hosted routes usually resolve cleanly, hiding the machinery.
Why two bridge channels? #
Primary plus fallback improves compatibility and reduces silent failures. One channel assumes a uniform world. Extensions live in a messy one.
Can this be bypassed? #
Bypassing route checks increases risk of false reports. It is not recommended. The five seconds of handshake buys the entire credibility of the run.
Does MCP bridge affect app runtime performance? #
It is test-path infrastructure and does not change normal user-facing runtime behavior. Visitors never touch it.
Run tests with MCP-aware flow ->
Next stall in the connecting phase, open the init payload before touching app code. The route metadata will tell you exactly which end of the line went quiet.